Storage and retention
Your backups go to a bucket you own or, if your plan includes it, to SafeGrd's own locked bucket (hosted storage). Either way, each backup is encrypted on your host before it leaves. Who can decrypt it depends on how your key is managed (Security and key custody). A bucket of your own has no per-gigabyte surcharge, and it stays in your account.
Choose a sink
| Sink | Notes |
|---|---|
| hosted | SafeGrd's own bucket, locked in compliance mode, with your plan's included storage. You have no bucket to set up. See Hosted storage. |
| local | A directory on the host. A filesystem-level lock stands in for Object Lock. Use it to try SafeGrd or on an air-gapped host. If the machine is lost, so are the backups. |
| AWS S3 | The reference target. Nobody can shorten or remove a compliance-mode lock on AWS, and SafeGrd's retention depends on that. |
| MinIO | Self-hosted and S3-compatible, with real Object Lock. Set endpoint. |
| Cloudflare R2 | S3-compatible. Set endpoint. It has no S3 Object Lock, so set worm_mode: "NONE" (details). |
| Backblaze B2, Wasabi | S3-compatible, each with its own object lock features. Check the bucket with safegrd doctor. |
| DigitalOcean Spaces | S3-compatible, but it has no Object Lock at all. You have to opt out of locking explicitly (details). |
| SFTP | A directory on an SSH server. It has no Object Lock, and it accepts worm_mode: "NONE" and nothing else (details). |
Set the sink once in config.yaml, or override it for one run with
--s3-bucket, --s3-endpoint, --s3-region and
--s3-prefix. You can also set a sink on a project, and every host in the
project uses it. When more than one is set, the per-run flags win over the project's sink,
and the project's sink wins over config.yaml.
safegrd doctor confirms the bucket locks. With worm_mode: "NONE", anyone with a delete key on the bucket can remove the snapshots.Hosted storage
Set storage.type: "hosted" and you have no bucket to set up. The host never
holds a storage credential. Each time it uploads a part or reads an object, it asks
SafeGrd's server for a URL signed for that one request: this part, of this many bytes, or
this version of this snapshot. The bytes go straight to SafeGrd's bucket. A signed URL
cannot delete, cannot be used for another object, and expires in minutes. The server locks
each snapshot in compliance mode, as in a bucket of your own, and the data is still
encrypted on your host.
Hosted storage is activated once your owner email is verified, so verify it before you run the first backup.
Included storage and overage
Your plan's included storage is counted in locked bytes. On the free plan, every byte kept
counts, locked or not. You cannot lift a lock to make room. safegrd doctor shows
how much is locked, and the console's Billing tab shows it against your included storage.
On a paid plan, a backup that goes past your included storage is still accepted. Once a day the server samples what you hold, and it averages the samples over the billing period. At the end of the period it charges for the part above your included storage, per GB-month, rounded down to whole GB. The price is on the pricing page. You get an alert at 80% and another when you pass your included storage. The console shows this period's overage so far, in dollars.
Locked bytes count until their lock ends. If you lower a retention or move to a smaller plan, the locks already written keep their dates, and overage on those bytes continues until each lock ends. The console shows the date the last one ends.
On the free plan and during the trial, there is no subscription to bill. A backup that would pass your included storage is refused with the reason, and you get an alert. If a subscription lapses, you can go a little past the last paid plan's included storage (the terms give the margin). After that, backups are refused. Nothing already stored is affected, and you can always restore.
How long hosted backups are kept
If your config sets no retention, the plan's applies. Every backup gets a short lock, and
daily, weekly and monthly copies are kept longer. The lengths are sized so a typical estate
fits in the plan's included storage. You can set your own retention_days and
keep_* within the plan's range. The server sets every lock, and never longer than
the plan's longest tier.
On the free plan, a backup is kept for 1 to 7 days (7 unless you choose otherwise) and locked for its first day. After that day it stays in the bucket unlocked until its retention ends, and it counts against your included storage until it is deleted. Each backup is a full copy, so each one can be deleted on its own date.
A snapshot is deleted when its retention ends, which on a paid plan is when its lock expires. SafeGrd removes the object from the bucket within 24 hours after that. While a snapshot is locked, nobody can change or delete it. Its verification records and Fire Drill certificates stay in the console, marked expired. To keep snapshots longer, export them to your own bucket before the lock expires.
Download a backup
You can download up to four times your included storage a day, or as much as you hold if
that is more. The limit covers every restore and Fire Drill, and a full
safegrd export to your own bucket.
To download a full backup, open its details in the console. Click Download backup,
Download metadata or Download RECOVERY.md (the
recovery document). The backup arrives encrypted, straight from
the bucket. Save the backup and its metadata in one folder and run
safegrd restore --from <snapshot id>.safegrd --target <database URL>
(or --target-dir for files and mail). If the host has a SafeGrd-managed key, run
the restore on one of your enrolled hosts, because SafeGrd releases the key only to them.
An incremental snapshot has no backup file to download. Files, PostgreSQL and SQLite back up
incrementally unless the surface is set to Full. Each run is stored as chunks it shares with
the other runs of its month. For these, the console offers the metadata and RECOVERY.md.
Restore one on a host with safegrd restore --snapshot <snapshot id>, or copy
it to your own bucket or a directory with safegrd export. MySQL and MongoDB
backups are always full.
Move to your own bucket
You can move whenever you like. safegrd export --to-bucket <yours> copies
every snapshot across, still encrypted and still locked. Then switch
storage.type.
WordPress sites and databases SafeGrd backs up, in your own bucket
A WordPress site, or a PostgreSQL database that SafeGrd backs up without a host of yours, can back up to the project's own bucket. SafeGrd holds that bucket's key and signs each upload and read with it, the same way it signs them for hosted storage with its own key. Neither the site nor the database backup is ever given the key. All of these have to be true:
- You set up the bucket in the console, and SafeGrd holds its key. A bucket that a host registered from its own config does not count.
- Test passed with that key and found Object Lock on, unless you saved the bucket without it.
- For a database SafeGrd backs up, the lock mode is Compliance or Governance. A WordPress
site can also use a bucket you set up with
worm_mode: "NONE"(no Object Lock).
Until then, a site backs up to hosted storage. The surface's panel in the console, the
plugin's Tools page and wp safegrd status tell you which condition is missing.
You can add a database SafeGrd backs up to such a project only once all of them are true,
and only as an incremental backup. A full backup is one archive, and SafeGrd writes those
only to hosted storage. MySQL and MongoDB are added to a project on hosted storage.
In your bucket, each backup is locked for the project's retention, in the bucket's lock mode. In a bucket without Object Lock, a site's backups are not locked, and the plugin and the console show them as Not locked. SafeGrd reads backups by name, so the bucket does not need versioning.
Hosted storage's included amount, plan retention and download limit do not apply in your
bucket. SafeGrd deletes nothing there. Your bucket's lifecycle rule does, or
safegrd prune on a host with the key.
The backups are under <prefix>/<node id>/repo/, the same layout a
host writes. An enrolled host with the bucket's key can run safegrd verify and
safegrd restore on them straight from the bucket. When the project moves between
hosted storage and its bucket, the next backup uploads everything once. Older backups stay
where they were written.
Storage forecast
Open Projects in the console and click Storage on a project. It shows what the project's storage holds now, and what it will hold once every surface has run through its retention. On hosted storage, it also shows the date you will reach your plan's included storage.
- Held now is every backup still locked. On hosted storage, it adds up the sizes the bucket reported and leaves out uploads still in progress. For your own bucket, it adds up the encrypted sizes your hosts reported, so it is an estimate. An incremental snapshot counts the bytes it wrote.
- Settles at multiplies what each surface writes per day by how long each backup is held, and adds up the surfaces. A surface that started recently is still filling up, so today it holds less than this.
- Full on is the first day the forecast passes your included storage. On a plan that bills overage, that is the day billing starts, and backups continue.
The forecast replays the last 30 days. It assumes each backup written in that time is written again 30 days later, at the same size and with the same lock. What is already stored drops out on the day its lock ends. A surface that has backed up for less than 30 days is replayed over the time it has run. Because it replays what your hosts wrote, the forecast includes compression, the longer locks on weekly and monthly copies, and an incremental surface's larger first run each month. It does not predict growth. When a database grows, its backups grow, and the forecast follows.
A surface with no backup yet is listed but not counted. On a bucket without Object Lock, a surface with no retention set is not counted either, because nothing removes its backups. To bring the figure down, shorten retention, back up less often, or move a surface to another project's storage. For your own bucket, the Object Lock cost calculator turns a schedule and retention into a monthly bill.
Setting up an AWS S3 bucket
- Create the bucket with Object Lock enabled. You can only turn it on when
you create the bucket. A bucket made without it cannot be converted, so you would have to
replace it.
aws s3api create-bucket --bucket acme-safegrd --object-lock-enabled-for-bucketOutside
us-east-1, add--create-bucket-configuration LocationConstraint=eu-west-1(your region). - Create an access key with the policy below for each backup host, and one read-only key for recovery.
- Run
safegrd doctoron the host. It checks that the bucket answers and that Object Lock is on. The firstsafegrd backupproves the key can write.
What a backup host needs. These are the S3 calls the CLI makes, and no others:
That policy cannot delete anything. s3:AbortMultipartUpload only abandons an
upload that failed halfway, so you are not billed for its parts. It cannot touch a finished
object. A compromised host cannot hide a backup behind a delete marker either. The only
SafeGrd command that deletes is prune, and it is off until you turn it on
(below).
The console's setup wizard writes this policy with your bucket's name for AWS, Wasabi and
MinIO, and the matching key command for B2. For AWS it also gives you a CloudFormation
template and a Terraform file. Both create the bucket with Object Lock and versioning on and
public access blocked. The API returns the same text at
GET /api/v1/storage/bucket-setup?provider=aws&bucket=acme-safegrd.
A recovery machine needs only to read and list:
The recovery runbooks use this key.
A colder storage class
Set storage.storage_class to choose the S3 storage class of each archive:
STANDARD (the default), STANDARD_IA or GLACIER_IR. A colder
class costs less to hold but charges for each GB read, and every Fire Drill reads one copy.
It also has a minimum billed period (30 and 90 days on AWS), and you pay for that period even
when the lock is shorter. Price your schedule and drills in the
Object Lock cost calculator before you change
the class.
The manifest beside each archive stays STANDARD, because every list and drill
reads it. Incremental (format: repo) surfaces are not affected. Glacier Flexible
Retrieval and Deep Archive are refused, because a drill could not restore from them.
Cloudflare R2
R2 is Cloudflare's S3-compatible store, with no egress fees. It has no S3 Object Lock API. It
refuses PutObjectLockConfiguration, so SafeGrd cannot lock a backup there or
read a lock back. Set worm_mode: "NONE", as for any
bucket without Object Lock.
- Create an R2 bucket in the Cloudflare dashboard.
- Under Manage R2 API Tokens, create an API token with Object Read & Write access for this bucket only. R2 tokens cannot be narrowed further, so this one can also delete.
- Set
AWS_ACCESS_KEY_IDandAWS_SECRET_ACCESS_KEYin your environment. - Point the endpoint at your account URL:
R2 has bucket locks
of its own. A bucket lock keeps objects from being deleted or overwritten for a period you
set on the bucket, from the dashboard or with
npx wrangler r2 bucket lock add <bucket>. If you want one, make it at least
as long as retention_days. SafeGrd cannot see the rule, so the console still
marks each snapshot Not locked: the bucket has no Object Lock. Anyone with
permission on the Cloudflare account can remove the rule.
Run safegrd doctor before the first backup to check the connection.
MinIO (self-hosted WORM)
MinIO has real S3 Object Lock when it runs in multi-drive or distributed erasure-code mode.
- Create a bucket with Object Lock on, using
mc:mc mb --with-lock myminio/safegrd-backups - Set a default retention:
mc retention set --default COMPLIANCE 30d myminio/safegrd-backups
- Save the AWS backup policy above, with your bucket's name, as
safegrd-backup.json, and give the backup hosts a user that has only it:mc admin policy create myminio safegrd-backup safegrd-backup.jsonmc admin user add myminio safegrd-backup CHOOSE-A-SECRET-KEYmc admin policy attach myminio safegrd-backup --user safegrd-backup - Add the sink to
config.yaml:
safegrd doctor calls GetBucketObjectLockConfiguration to check the lock mode.
Backblaze B2
B2 has Object Lock, which it calls File Lock. Turn it on when you create the bucket, because it cannot be added later.
- Create a B2 bucket with File Lock (Object Lock) enabled.
- Create an application key limited to that bucket, with only the capabilities a backup needs. Without
deleteFiles, the key cannot delete or hide a file:b2 key create --bucket acme-b2-safegrd safegrd-backup listBuckets,readBuckets,readBucketRetentions,listFiles,readFiles,writeFiles,writeFileRetentions - Find your region endpoint (for example,
s3.us-east-005.backblazeb2.com). - Configure the sink:
Wasabi
Wasabi has S3 Object Lock in compliance mode, and no egress fees.
- Create a Wasabi bucket with Enable Object Lock turned on in Compliance Mode.
- Under Policies, create a policy with the AWS backup policy above, with your bucket's name. Wasabi reads the same document. Create a user for the backup hosts, attach the policy, and make an access key.
- Set the endpoint for your region:
DigitalOcean Spaces, and any bucket without Object Lock
Spaces has no Object Lock. SafeGrd works there: snapshots are encrypted to your key, and Fire
Drills test them as usual. But nothing stops them from being deleted. Anyone
with a key that has delete permission on the Space can remove them. To use a Space, set
worm_mode: "NONE" in the config:
safegrd init writes the same from flags:
The Space's key comes from AWS_ACCESS_KEY_ID and AWS_SECRET_ACCESS_KEY
in the host's environment, or from access_key_id and secret_access_key
under storage.
Without worm_mode: "NONE", a backup to Spaces fails at startup, so an unlocked
backup is never reported as locked. With it, the console marks each snapshot
Not locked: the bucket has no Object Lock, and the CLI never prints an
immutability date. safegrd doctor reports it as a warning:
worm_mode is NONE: snapshots in this bucket can be deleted by anyone with delete
  permission
. On a bucket that should lock and does not, safegrd doctor
fails with bucket ... cannot be confirmed to lock and tells you what to change.
Hand out as few keys to the Space as you can, write-only where possible. Consider also copying to a bucket that does lock.
An SFTP server
You can back up to a directory on any SSH server that offers SFTP, such as a NAS, a storage
box or a machine of your own. Every surface type works there, in both formats (incremental
and format: tar). Restores and Fire Drills read from it the same way as from a
bucket.
An SFTP server has no Object Lock, so set worm_mode: "NONE". A config with any
other value, or with none, is refused when it is read. Each
snapshot records the date it is kept until, and the CLI never prints a lock date for it.
path is the directory backups go in, either absolute or relative to the
account's login directory. Sign in with private_key (a key without a
passphrase) or password. Both take env:VAR or
file:/path, so the secret stays out of the config.
The CLI checks the server's host key before it sends anything. You can list the server in an
OpenSSH known_hosts file: run
ssh-keyscan -p 22 backup.example.com >> /etc/safegrd/known_hosts, then
compare the fingerprints with the server's administrator. Or pin the key's fingerprint in
place of known_hosts:
If the server's key does not match, or known_hosts does not list the server, the
CLI refuses to connect, and the error shows the fingerprint the server presented. Give
known_hosts as a full path, because the daemon runs as its own user, and that
user's home is not yours.
Give the account write access to path and nothing else. Anyone who can sign in
as that account can delete the backups in it, so keep its key or password on the host that
backs up.
safegrd init does not write an SFTP block. Run it with
--storage local, then replace the storage block with the one above.
safegrd doctor signs in, lists the directory and reports that the server has no
Object Lock. WAL archiving for point-in-time recovery does not use SFTP: it needs a bucket,
hosted storage or a local directory.
How WORM retention works
--retention-days sets an S3 Object Lock retention period on each object
as it is written. In compliance mode, the default, nobody can delete or
overwrite the object until retention expires. That includes the account's root user and
SafeGrd. Stolen administrator credentials cannot remove a locked backup either.
You cannot shorten or undo a lock.
Once a compliance lock is set, nobody can shorten or cancel it. With a long retention on
hourly snapshots, you pay for storage you cannot delete until each date passes. Try a short
retention_days on a small dataset first.
worm_mode: "GOVERNANCE" is the softer mode. Anyone holding the bypass
permission can shorten a lock. It protects against accidents, but an attacker with that
permission can remove the backup.
Keeping daily, weekly and monthly backups longer
You can keep some backups longer than others (grandfather-father-son). Set the tiers on a
surface or under defaults:
- The tier is decided when the backup is written, because an Object Lock period can never be shortened later. The first successful backup in a day, week or month takes that slot. A failed backup does not, so the next successful one takes it instead. The daemon logs which backup took a slot. On an hourly schedule, this keeps storage small: the hourly copies need only a short lock, and one backup a day carries the history.
- If the daemon loses its state (a new host, a wiped state directory), the next backup takes the slots again. One backup may then be kept longer than planned, never shorter.
- SafeGrd still never deletes a locked backup. The tiers decide how long each one is protected. A lifecycle rule on the bucket decides when it is deleted (see Listing and expiry below).
- A one-off
safegrd backup --database-url,--filesor--emailapplies the tiers underdefaultstoo, or the ones you pass as--keep-daily,--keep-weeklyand--keep-monthly. It records which day, week and month already have their copy, per source and bucket, inone_off_slots.jsonin the state directory (~/.safegrdunlessdaemon.state_dirsays otherwise). A nightly cron line gets the same weekly and monthly copies a surface does. - If you pass
--retention-daysand no--keep-*flag, the backup is locked for exactly that many days and the config's tiers do not apply. The flag says what the lock is, and a lock cannot be shortened afterwards. - Under
worm_mode: "NONE"nothing is locked, so the tiers protect nothing, and the daemon does not claim tier slots.
Locking only the kept copies
When you create a project, you choose which of its backups are locked. The organization's first project locks every backup. A project you create after that can lock only the copies it keeps:
- The first backup of each day is locked when it is written, for the daily tier. On Scale, the first backup of each 6-hour slot is locked.
- The weekly and monthly copies are chosen once the week or month has ended, from backups
that a Fire Drill restored and Threat Shield did not flag. Each is locked for its tier. If
none qualifies, the newest scheduled backup is kept anyway, marked not drilled, and you
get one alert (
kept_undrilled). - The backups in between are written unlocked and kept for the plan's retention. For one
of these,
safegrd backupprints "Kept until <date>, not locked", and the console lists it as Recent. On hosted storage, they count at half against your included storage. - Nothing is deleted while a month is open. Once the month's repository is closed and the
retention has passed, SafeGrd removes the unlocked objects that no kept copy references.
In your own bucket, this needs the opt-in prune
(Keep one snapshot longer and
safegrd prune). Without it, unlocked objects stay in the bucket. - While a Threat Shield anomaly is open, the objects of the last known good backup are locked 14 days ahead, and locked 14 days ahead again every day.
- You cannot change a project's rule. To move a surface to the other rule, create a project and enroll its hosts there.
- The rule applies to file and database surfaces, on hosted storage and in your own
bucket. In your own bucket, the host applies it with its own key. Mailboxes and
format: tarbackups lock every copy, whatever the project's rule.
Sinks with no Object Lock
Use worm_mode: "NONE" for storage with no Object Lock, such as DigitalOcean
Spaces. SafeGrd never switches to unlocked storage on its own. A backup to a bucket without
Object Lock fails at startup unless this setting is there. With NONE, snapshots
are written unlocked. The value is case-sensitive: COMPLIANCE,
GOVERNANCE or NONE.
Listing and expiry
In your own bucket, SafeGrd deletes nothing until you turn pruning on. (Hosted storage prunes a snapshot once its retention ends.) When a lock expires, the snapshot may be deleted, but it stays until something prunes it. With pruning off, the bucket and its bill grow with every backup. A surface's panel in the console shows what it keeps now and what it will keep once its copies have rolled over. How fast it grows is in the storage forecast.
A local directory is never pruned. Once you no longer need its snapshot files, anyone who can write to the directory can delete them.
To let expired snapshots go, set storage.expire_after_lock: true and the daemon
prunes once a day. Or run safegrd prune yourself (with --dry-run
first).
Pruning deletes a snapshot only after its Object Lock ended more than a day ago. It judges
that by the bucket's own clock and the lock the bucket itself reports, not by the host's
clock. It keeps the newest three snapshots of each surface whatever their locks say
(--min-keep), so a short retention never empties a surface. It also keeps the
last known-good snapshot while Threat Shield reports an open anomaly. If SafeGrd's server
is unreachable, nothing is pruned.
Pruning needs s3:DeleteObjectVersion, s3:GetObjectRetention and
s3:GetObjectLegalHold on the host's key. The wizard adds these when you turn on
expiry. With them, the key can delete any snapshot whose lock has ended, and it still cannot
touch a locked one. The bucket enforces the lock. min_keep and the anomaly hold
are enforced by safegrd itself, so set retention_days to the
furthest back you would need to restore. Neither the backup policy nor the recovery policy
grants s3:DeleteObject, so a host's key cannot write a delete marker over a
snapshot.
Use pruning instead of a bucket lifecycle rule, because a lifecycle rule cannot tell the daily, weekly and monthly tiers apart.
retention_days: 14 on one snapshot. The daemon prunes once a day, and keeps the newest three snapshots of each surface whatever their dates.
An SFTP server has no lock. There, safegrd prune and
expire_after_lock delete a snapshot one day after the keep-until date it
records. The day is judged by the server's clock: the time it stamps on a file it has just
written. The newest min_keep snapshots and the anomaly hold apply there too.
Keep one snapshot longer
You can extend a snapshot's lock up to 13 months from today, before a migration or because an auditor asked for it. Extending is the one change Object Lock allows. Nobody can shorten the lock afterwards, SafeGrd included.
On hosted storage, an owner or admin picks the date under the snapshot's Details in the console. The kept snapshot counts against your hosted storage for as long as it is locked.
In your own bucket, run
safegrd keep --snapshot <id> --until 2027-01-31 --yes on a host that writes
to it. The host's key needs s3:PutObjectRetention and
s3:GetObjectRetention. The console shows the new date once the host reports it.
The backup file, its metadata and its recovery document are extended together. An incremental snapshot shares its chunks with the rest of its month, so it is kept as long as that month and cannot be kept on its own.
When a project changes buckets
If you move a project to another bucket, or to or from hosted storage, or delete an
organization, the backups already written stay where they are. SafeGrd records what was left
behind. The key access log gets a sink_released entry naming every snapshot SafeGrd
recorded in the old location, and the console tells you the same when you make the change.
In your own bucket, your lifecycle rule or safegrd prune removes them once their
locks end. Hosted storage removes each one when its lock ends.
A second bucket
You can have every backup written to up to two more S3 buckets, in another account, at another provider or in another region. Each bucket has its own access key, lock and retention. Every copy is encrypted to the same Age key as the first, so the key that restores one restores them all.
Add a bucket in the console
On Growth and Scale:
- Create the bucket at your provider. Turn on Object Lock if you want its copies locked. Make an access key that can write to it.
- Open Projects, click Storage on the project, and go to More buckets.
- Click Add bucket. Give it a name, such as
offsite, and fill in the bucket, endpoint, region and keys. - Choose its lock and how many days to keep each backup. Click Test, then Save.
Every host in the project writes to the bucket from its next backup. SafeGrd holds the bucket's key, encrypted, and gives it only to your enrolled hosts.
Or list it in the host's config
This works on every plan. Add the buckets under copies: in the host's config:
Every surface on the host writes to every bucket in the list. To choose for one surface, set
copies: [offsite] on it, or copies: [] for none. If the project has
buckets set in the console, those replace this list, and the host says so on each run. Every
key is listed in the config reference.
See what each bucket holds
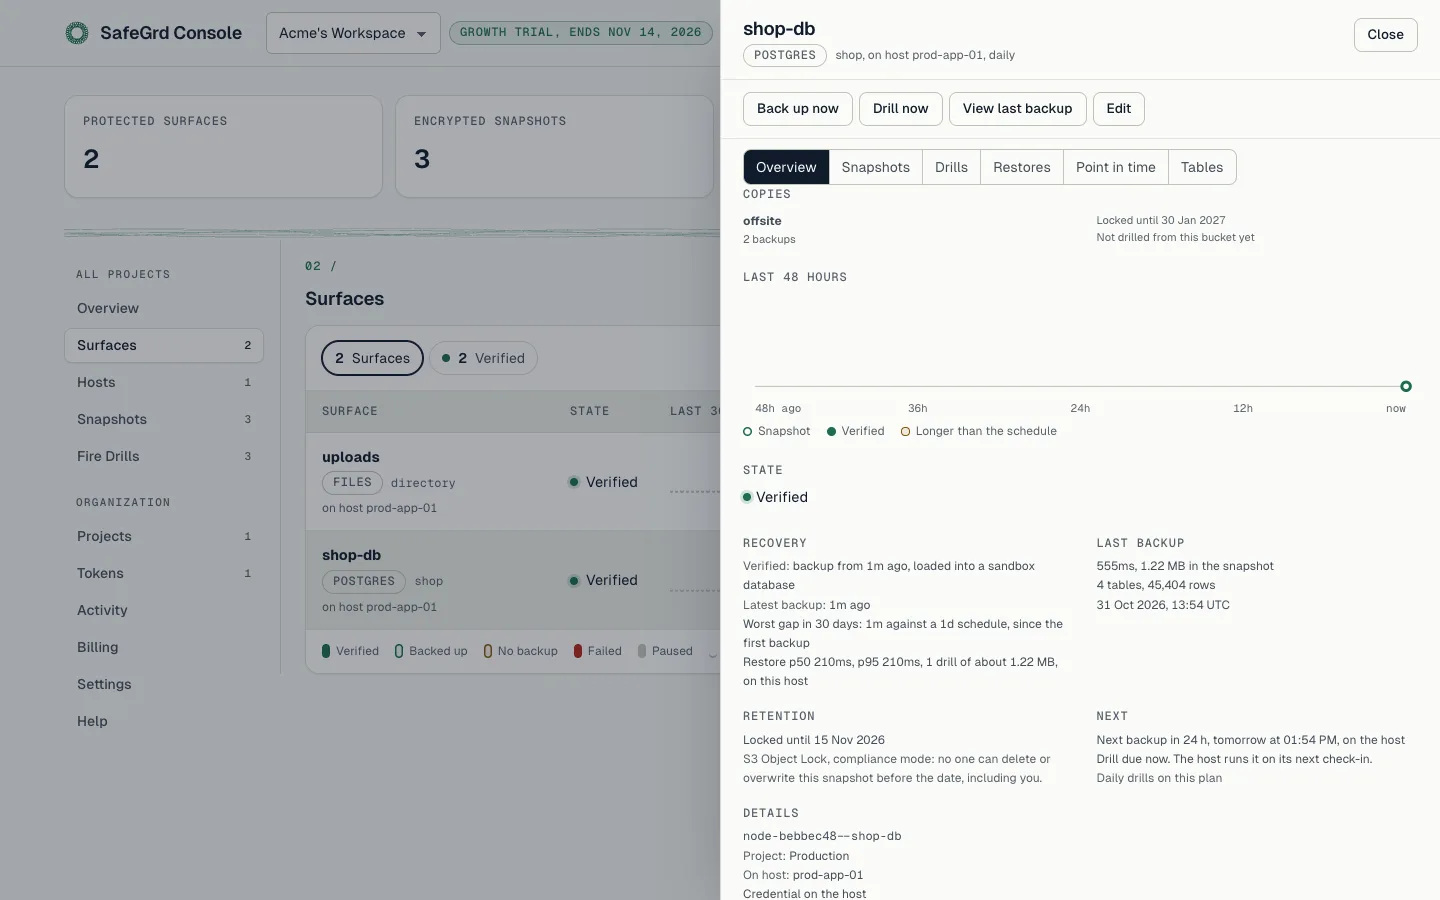
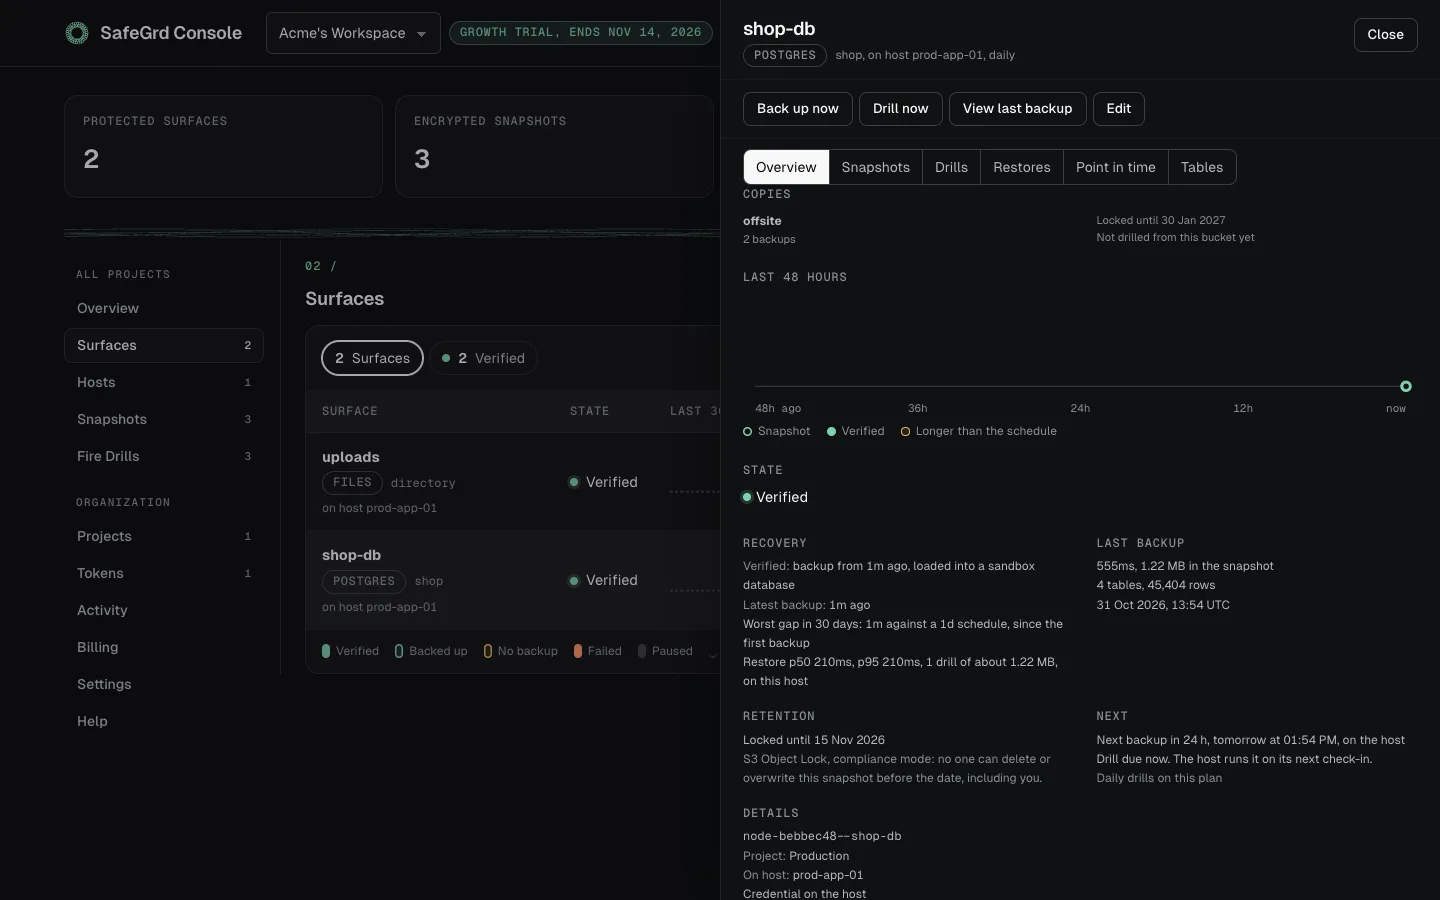
Each snapshot in the surface's Snapshots tab says how many copies it has,
such as "2 of 2 copies". If a bucket is behind, the surface shows Copy behind.
On the host, safegrd copies status lists what each bucket lacks.
How a backup reaches each bucket
- A full backup is one archive file. It is written to every bucket at once, from the same encrypted stream. Nothing is read back out of your own bucket.
- An incremental backup is written to every bucket during the run, object by object, as the host reads it. If a bucket missed part of the month's backups (it was down, or you added it mid-month), it is filled after the run from your own bucket. Your provider bills that read as egress. Databases back up incrementally unless the surface was added with full backups.
- Each bucket locks a backup with its own
worm_modeandretention_days. An incremental run stays locked for the bucket's retention from the end of its month. A bucket set toNONEis shown as not locked.
When a bucket is down
If one bucket is down, the backup still succeeds on your other buckets. The host prints
Warning: copy to offsite failed, and the surface shows
Copy behind. The daemon tries every half hour, and once the bucket answers,
it writes what the bucket lacks. After a day behind, you get a copy_behind
alert, and a copy_caught_up alert when the bucket holds every backup again. To
catch up now, run:
Restore from a copy
A copy holds the same files as your own bucket, so you restore from it the same way:
verify, list and find take --from-bucket too.
Without SafeGrd, you restore from a copy the same way as from your own bucket
(runbooks). To test that each copy restores, set
drill.source: rotate on the surface. Each Fire Drill then reads the next bucket,
and its certificate names the bucket it read.
Limits
- A surface that SafeGrd backs up without a host of yours is not copied to more buckets yet.
- You cannot move or remove a bucket in the console while it holds locked copies. Add a new bucket under another name instead.
A recovery document beside every snapshot
Every snapshot is written with two files beside it: SNAPSHOT.meta.json (the
manifest) and SNAPSHOT.RECOVERY.md, a plain-text recovery page. The page says:
- where the snapshot is (bucket, endpoint, prefix)
- what a restore needs: the server version, and the extensions and roles to have ready
- the commands that restore it, with
safegrd restoreand, for PostgreSQL, withpsqlalone
It is written for someone who has the bucket and the key and nothing else. So it is not encrypted, and it holds no secret: no credential, no key and no connection string.
For a full backup, the two files sit next to its archive. For an incremental snapshot, they
sit in the snapshots/ folder of its month's repository,
repo/<surface>/<epoch>/snapshots/. On hosted storage, download them
from the snapshot's details in the console.
Set recovery_doc_sealed: true on a surface to seal the recovery page with the
surface's recipient instead, as SNAPSHOT.RECOVERY.md.age. Both forms are locked
like the manifest. If the recovery document cannot be written, the CLI says so on stderr,
and the backup still succeeds.
Someone deleted my backups
You can bring them back with safegrd undelete. In a versioned bucket with Object
Lock on, an ordinary delete cannot remove a locked object. S3 puts a delete marker
on top of it instead. The marker hides the snapshot from normal listings, and the data stays
where it was.
safegrd undelete --all rolls a versioned bucket back to before the deletion.
Every snapshot and sidecar is visible again once its delete marker is gone. Nothing is
re-uploaded, so the rollback takes seconds however much the bucket holds.
The command removes only delete markers, each addressed by its version id. It cannot remove a version that holds data, so it is safe to run twice. If it finds nothing to remove, it tells you why: either the snapshot is there and was never hidden, or the id is not in that bucket at all. In the second case it names the bucket, prefix and node it searched, and exits non-zero.
Removing a delete marker needs s3:DeleteObjectVersion. A host's key has that
only when expiry is on, so run the command with an administrator's key. Afterwards, deny
s3:DeleteObject to the credential that made the deletion.